pyscan

What is a spatial scan statistic?

populationcases (confirmed COVID-19)

The real spread of COVID-19, from the Wuhan cluster on 31 December 2019 to 31 March 2020. Black dots show where people live; each red dot is about 100 confirmed cases. Planes fly the first documented routes, and on 11 March the WHO declares a pandemic. At the end of March the scan settles on a window around the Alps. Data: Johns Hopkins CSSE; Italy, Protezione Civile. Earth: NASA Blue Marble.

Say we want to know where COVID-19 cases were unusually dense, and by how much. The black dots show where people live: that’s the population, b. The red dots are confirmed cases: we call them m. The scan slides a window over the map, at every size and position, and gives every window a score, Kulldorff’s log-likelihood ratio:

phi of Y equals m of Y times log of m of Y over b of Y, plus 1 minus m of Y, times log of 1 minus m of Y over 1 minus b of Y

Here m(Y) and b(Y) are the shares of all cases and of all people inside the window Y, and the expected share is what the same rate everywhere would give.

In plain English, for the window it found:

just over 1% of all people live here
so we expect just over 1% of the cases
17% of the cases are here

13× more than expected → high score

The scan keeps the window with the highest score.

Scan statistics are used to find cancer clusters, disease outbreaks such as COVID-19, emerging public-health threats and street crime: hotspots of cases, where they are and how unusual. The common tools work on points. SaTScan is the most widely used; for regions, it uses one point per region, typically the centroid. pyscan is a fast, open-source scanner, Python on a C++ backend, by my co-author Michael Matheny, and it is what we use.

The gap

Real data come as counts per region

The problem. Public-health and crime maps almost never come with addresses — you get one total for a whole county or zip code, and some counties are the size of a small state. The fastest algorithms for spotting a hotspot need actual points on the map, so the standard shortcut squashes each county down to a single dot at its center. That dot erases the county’s real shape and size — and a disease outbreak that a health department finds late, or not at all, is measured in lives, not in decimals of statistical power.

California counties shaded by Valley Fever rate, darkest in the San Joaquin Valley, outlined with a dashed line
Published · one rate per county
California with one red dot per county; the scan's red window covers only the southern part of the dashed valley
Centroid · one point per county
Valley Fever is a fungal infection. Its fungus lives in the soil of California's San Joaquin Valley (dashed), so we know where the hotspot should be. The state publishes one rate per county, with no addresses, for privacy. With one point per county, at its centroid, the scan's window misses most of the valley. Data: CDPH, 2014–2018.
Why it misses: one point stands for the whole region. Kern County, the big Valley Fever county: a window over 46% of it sees zero cases with the centroid, and 48% with 50 points. A ZIP code in Henderson, Nevada: the centroid is inside, but near a thin neck; a window over 68% of the ZIP code sees zero cases, and 68% with points. Henrico County, Virginia, wraps around the City of Richmond, so its centroid is not even in Henrico; a window over 58% of the county sees zero cases, and 58% with points. A region is not a point. The grey box is one scan window.

Existing methods

Existing ways to scan regions are lossy, slow, or capped
Counties drawn as one dot each, with a window that contains some dots whole
Centroid · fast, lossy
Counties shaded by their exact overlap with a window
Buchin et al. · exact, slow
A connected group of whole counties outlined as one cluster
FlexScan · whole regions, capped
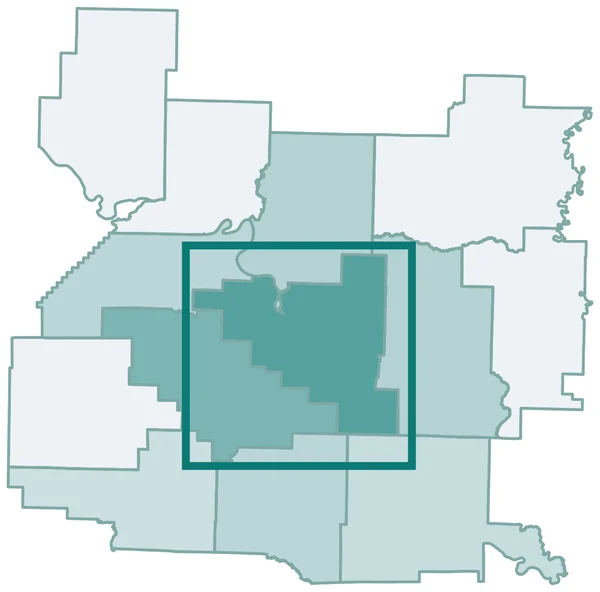
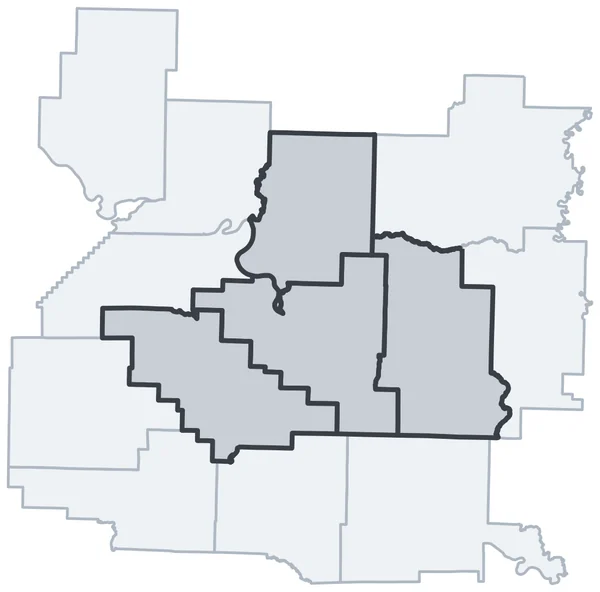
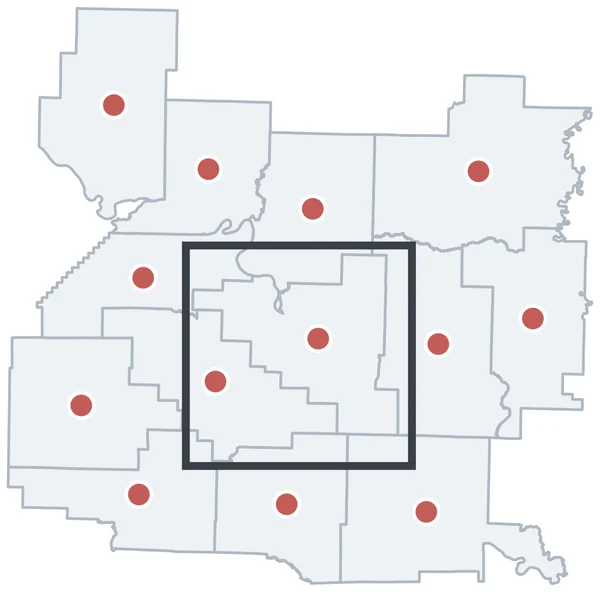
The centroid is fast, but each region becomes one dot, and a window sees all of it or nothing. Buchin and colleagues compute exactly how much each window overlaps each region: accurate, but slow, and the window size must be given in advance. FlexScan searches connected groups of whole regions, but it is slow, and its code caps a cluster at 15 regions. What is missing is a fast and accurate way to run point-based scanners on region data.

The method

Replace each region with 20–50 random points

If your data are counts per region, don't shrink each region to a single point. Scatter 20–50 random points inside it, and share the counts among them. Same data, same scan, far more statistical power — and with pyscan, almost no extra time.

For each region, draw k points uniformly at random inside it, with k between 20 and 50. Each point carries 1/k of the region’s cases and people (Geom k): with k = 20, a county with 120 cases and 10,000 people becomes 20 points with 6 cases and 500 people each. The region keeps its spatial extent, and the scan algorithm is untouched: it is a preprocessing step.
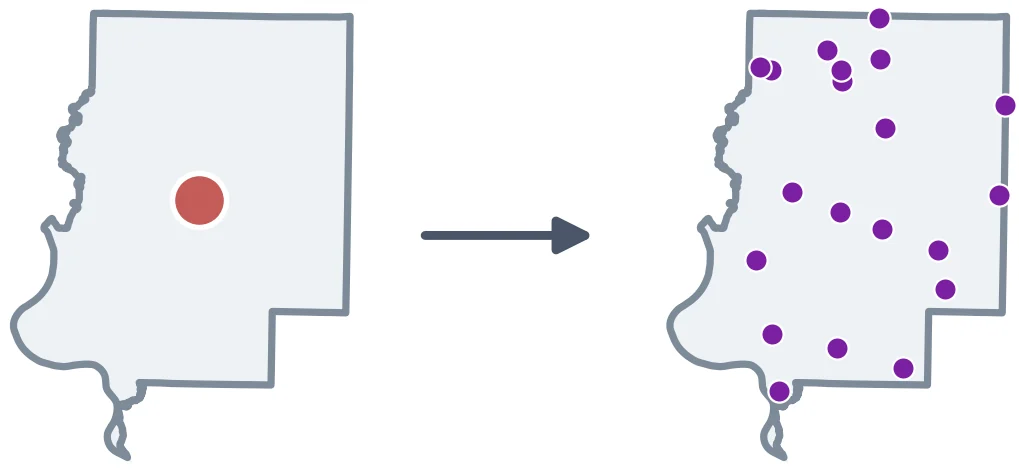
One county drawn twice: with a single red centroid dot, then, after an arrow, with 20 purple points spread inside it
120 cases
10,000 people
6 cases each
500 people each
Arkansas counties with one red dot each
Before · 75 centroids
Arkansas counties filled with purple sampled points, 20 per county
After · 20 points per county

How we solved it. Our fix is almost embarrassingly simple: instead of one dot at the center, scatter 20–50 points across the county’s actual shape and share its case count among them. The map gets its geography back, and the fast algorithms never notice the difference. The proof it works: given nothing but county totals of Valley Fever cases, the method redraws California’s San Joaquin Valley endemic region — a region fixed by soil ecology — far more faithfully than the centroid shortcut ever could, while scanning the entire continental-U.S. map — 3,711 region polygons spanning 3,108 counties — in 0.33 seconds, roughly 3,000× faster than FlexScan’s 1,109 s (scan step only; FlexScan additionally runs a significance test the other methods do not).

Speed

At national scale, the whole US scans in 0.33 s

The whole pipeline on the US map: the county borders, 50 points per county, a planted anomaly in red, and the scan trying windows of every size and position until it locks onto the anomaly. The moving windows are an illustration; the time is real. Satellite image: NASA Blue Marble.

Fifty times more points does not mean a much slower scan. pyscan’s time is set by a data-adaptive grid, not by the number of points:

Scan time, one discovery 1 point / region 50 points / region (ours) Buchin et al. FlexScan
USA (3,711 regions) 0.29 s 0.33 s 114 s 1,109 s
Arkansas (75 counties) 0.21 s 0.28 s 25.3 s 8.00 s

Scan step only, one discovery, same machine. The USA map is the county × congressional-district partition (3,711 regions). FlexScan's time includes a Monte Carlo significance test the others do not run; Buchin et al. sweeps nine window sizes.

Results

A synthetic test: plant a hotspot, see which input finds it

Arkansas centroids, orange for cases; the planted region in green and the found window, red dashed, too big and off-centre
Centroid · found window PJD 0.54
Arkansas with 50 points per county; the found purple window sits on the green planted region
50 points · found window PJD 0.08
Arkansas, one typical trial. Inside the planted region (green), each point is a case with probability p = 0.5; outside, with q = 0.2. The difference p − q is the signal strength. On centroids the scan finds a window too big and off-centre; with 50 points it lands on the planted region. The Point Jaccard distance (PJD) measures how much the found and planted windows disagree: 0 is perfect, and below 0.2 is a good match.
Point Jaccard distance against signal strength on Arkansas: the centroid and one-random-point curves stay above the 0.2 line, 5 and 10 points per region cross it at 0.45 and 0.30, and 50 points crosses it at 0.15
More points per region, better detection. Twenty trials at each signal strength on Arkansas; lower is better, and below the grey line is a good match. The centroid never gets there, and neither does one random point per region. With 5 points per region a good match comes at a signal of 0.45, with 10 at 0.30, and with 50 at just 0.15.
Six small charts, for Utah, California, Arkansas, Georgia, New York City and the contiguous US; on each, the 50-points curve drops below the good-match line before the centroid curve
Sampling wins on all six maps, from 29 to 3,108 regions: on each, 50 points per region crosses the good-match line first.
Point Jaccard distance against the planted region's size in Georgia: 50 points per region stays below the good-match line from 4.1% of the state; the centroid only reaches it at 60.8%
Georgia with nested planted rectangles from 4.1% to 60.8% of the state
In Georgia, a planted rectangle grows from 1.7% of the state to 60.8%. At 4.1%, 50 points per region find it and the centroid does not; the centroid succeeds only at 60.8%, the largest size tested. Sampling finds planted regions 15× smaller than centroids can.
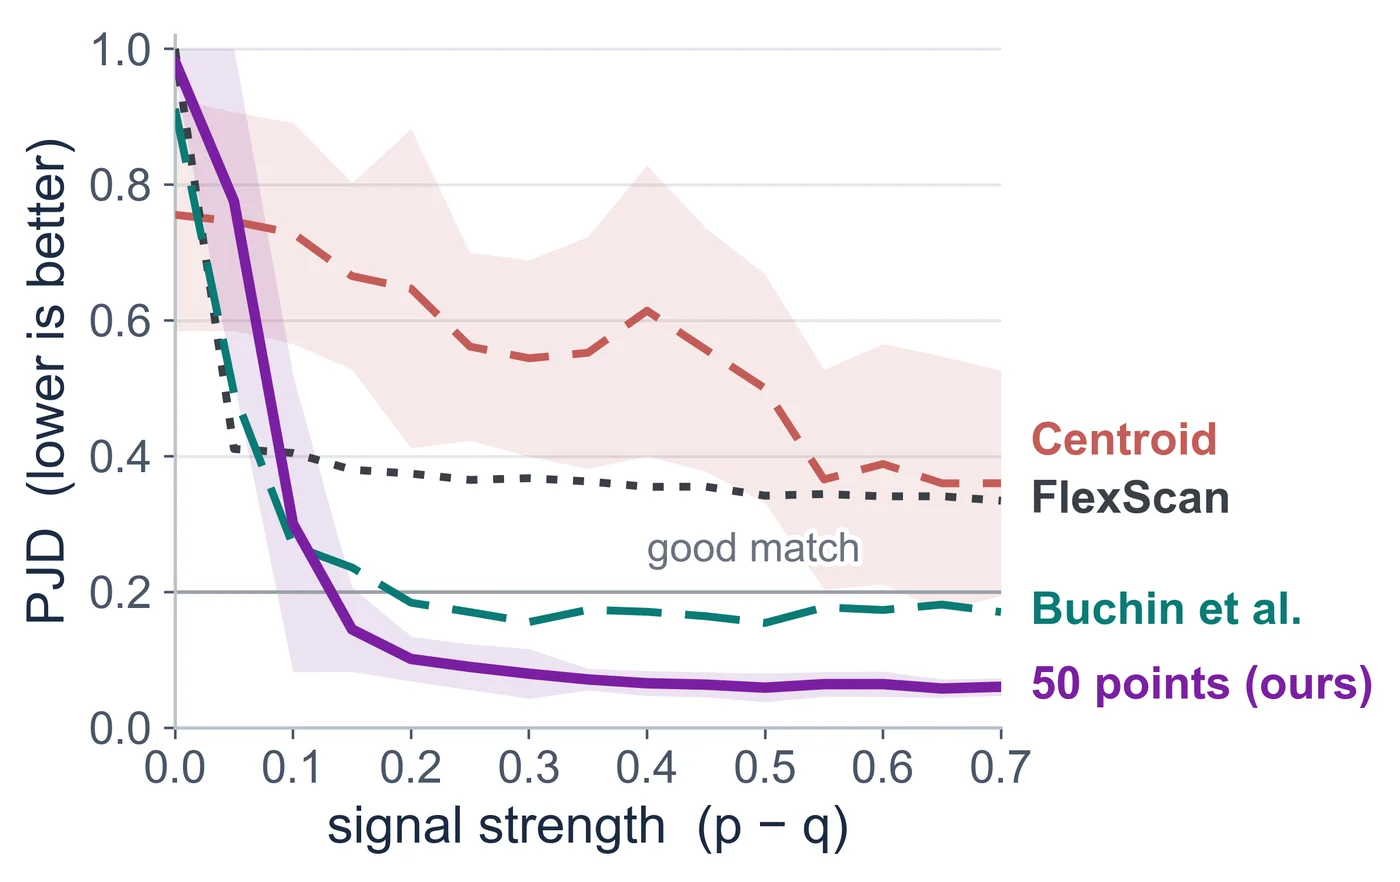
Point Jaccard distance against signal strength on Arkansas for the centroid, FlexScan, Buchin et al. and 50 points: FlexScan plateaus near 0.35, Buchin et al. gets just below 0.2, and 50 points goes well below it
Against the region methods on the same Arkansas test. FlexScan's own code caps a cluster at 15 regions; the planted region spans more than 15 counties, so it plateaus near 0.35. Buchin and colleagues' code takes one window size per run and cannot find the size; run with the authors' protocol, nine sizes around the true size, which is its best case, it gets just below the line, but 90× slower than ours. Ours has no cap and no size input, and goes well below the line.
Point Jaccard distance against points sampled per region, for six maps, with a 1 over root k reference line; the US reaches a good match at k=3 and Utah at k=75
The finest maps need the fewest points. At a weak signal (0.15), the first k that reaches a good match is 3 for the US, 7 for New York City, 20 for California, 50 for Arkansas and Georgia, and 75 for Utah. A convergence analysis in the paper explains why: as a map is divided into more regions, fewer sample points per region are needed, and the error roughly follows 1/√k.

Real data

Valley Fever: within 0.036 of the best rectangle

California with 50 sampled points per county; the scan's purple window covers most of the dashed San Joaquin Valley
50 points per county
Distance to the valley against points sampled per county: the centroid at 0.717, 50 points at 0.448, and the best axis-aligned rectangle at 0.412
The ground truth is the eight San Joaquin Valley counties, fixed by the soil, not by the counts. With 50 points per county, the scan's window sits on the valley: its Point Jaccard distance to the truth drops from 0.717 with the centroid to 0.448, within 0.036 of 0.412, the best any axis-aligned rectangle can do, because the valley runs diagonally.

Talk

Slides

Slide 1 of 50: Sampling for Region-Aggregated Spatial Scan Statistics. Foad Namjoo (University of Utah), Drew McClelland (Taptap Send), Michael Matheny (Meta) and Jeff M. Phillips (University of Utah). ACM SIGSPATIAL, Riverside, California, November 5, 2026.
Slide 2 of 50: What are spatial scan statistics? The title alone, before the globe.
Slide 3 of 50: What are spatial scan statistics? An animated globe of confirmed COVID-19 cases from 31 December 2019 to 31 March 2020 (Johns Hopkins CSSE; one red dot is about 100 cases): black dots show where people live, and at the end the scan's magnifying glass settles on Europe.
Slide 4 of 50: How is a window scored? A window around the Alps holds 1.3% of the population and 17% of the cases: 13 times more than expected, so it gets a high score.
Slide 5 of 50: The Kulldorff score: count the people and the cases. A window Y on a map of 20 people, 5 of them cases. 4 of the 20 people are in Y (b = 0.2) and 3 of the 5 cases (m = 0.6).
Slide 6 of 50: The same window, scored. Inside Y, 1 case is expected and 3 are found; outside, 4 are expected and 2 found. φ(Y) = 0.66 − 0.28 = 0.38: a hotspot.
Slide 7 of 50: A window with 4 of the 20 people and 1 of the 5 cases: inside and outside, the cases found match the cases expected, so φ(Y) = 0, no hotspot. The scan keeps the window with the highest φ.
Slide 8 of 50: The common tools work on points: each person and each case is a point. SaTScan, the most widely used, takes one point per region, the centroid, our main baseline. pyScan, which we use, is open source, Python on top of C++, and scans rectangles and disks over points.
Slide 9 of 50: For privacy, real data come as counts per region. The title alone, before the map.
Slide 10 of 50: For privacy, real data come as counts per region: Valley Fever cases per 100,000 a year by California county (CDPH 2014–2018), highest in the San Joaquin Valley.
Slide 11 of 50: The same map with one point per county: the centroid baseline.
Slide 12 of 50: One point cannot stand for a whole region: Kern County, California; ZIP code 89044, Nevada; and Henrico County, Virginia, each as one centroid and as 50 points. In the animation a window covers part of each region: the centroid sees all of its cases or none, while the 50 points see about the share covered (Kern County: the window covers 46%, the centroid sees 0 cases, the points 48%). Last, Henrico County's centroid falls in Richmond, outside the county.
Slide 13 of 50: Our method: 50 random points per region. A region with 100 cases and 10,000 people is split into k=50 points; each point carries 2 cases and 200 people.
Slide 14 of 50: 50× more points, but still fast. Scan time for the USA (3,711 regions): 0.29 s with 1 point, 0.33 s with 50 points, 114 s for Buchin et al. and 1,109 s for FlexScan. Arkansas (75 counties): 0.21 s, 0.28 s, 25.3 s and 8.00 s.
Slide 15 of 50: At national scale, every county becomes 50 points and the scan finds the hotspot: an animation over the contiguous United States, ending on the scan's runtime, 0.33 seconds.
Slide 16 of 50: How we test: we plant a hotspot. Inside a box each person is a case with probability p=0.5, outside it with q=0.2; the signal is p − q=0.3.
Slide 17 of 50: How we test: we score the window the scan finds by its Point Jaccard distance to the planted box, 0 for a perfect match and 1 for no overlap. Five examples, from 0.67 (a miss) to 0.10 (a good match).
Slide 18 of 50: A synthetic test on Arkansas: where is the hotspot? One point per county (the centroid) beside 50 points per county, with dots for people and for cases.
Slide 19 of 50: The same two maps with the planted hotspot as a green box: inside it each person is a case with probability p=0.5, outside it q=0.2.
Slide 20 of 50: 50 points find the hotspot; the centroid does not. On Arkansas the centroid's window has a Point Jaccard distance of 0.54; with 50 points per county it is 0.08.
Slide 21 of 50: More points, better detection: Point Jaccard distance against signal strength on Arkansas, first for the centroid and one random point alone.
Slide 22 of 50: More points, better detection: 5 and 10 points per county added, below the centroid.
Slide 23 of 50: More points, better detection: Point Jaccard distance against signal strength on Arkansas. 5, 10 and 50 points per county fall well below the centroid and one random point.
Slide 24 of 50: Sampling wins on all six maps: Utah, 29 counties. Point Jaccard distance against signal strength; the sampled points beat the centroid.
Slide 25 of 50: Sampling wins on all six maps: California, 69 polygons. Point Jaccard distance against signal strength; the sampled points beat the centroid.
Slide 26 of 50: Sampling wins on all six maps: Arkansas, 75 counties. Point Jaccard distance against signal strength; the sampled points beat the centroid.
Slide 27 of 50: Sampling wins on all six maps: Georgia, 159 counties. Point Jaccard distance against signal strength; the sampled points beat the centroid.
Slide 28 of 50: Sampling wins on all six maps: New York City, 263 ZIP codes. Point Jaccard distance against signal strength; the sampled points beat the centroid.
Slide 29 of 50: Sampling wins on all six maps: the contiguous US, 3,108 counties. Point Jaccard distance against signal strength; the sampled points beat the centroid.
Slide 30 of 50: Georgia: we find regions 15× smaller. Start tiny: nobody finds it.
Slide 31 of 50: Georgia: still small, and 50 points per region find it; the centroid does not.
Slide 32 of 50: Georgia: the planted region grows (step 1 of 6), and each method's curve extends to the larger size.
Slide 33 of 50: Georgia: the planted region grows (step 2 of 6), and each method's curve extends to the larger size.
Slide 34 of 50: Georgia: the planted region grows (step 3 of 6), and each method's curve extends to the larger size.
Slide 35 of 50: Georgia: the planted region grows (step 4 of 6), and each method's curve extends to the larger size.
Slide 36 of 50: Georgia: the planted region grows (step 5 of 6), and each method's curve extends to the larger size.
Slide 37 of 50: Georgia: the planted region grows (step 6 of 6), and each method's curve extends to the larger size.
Slide 38 of 50: Georgia: the planted region grows again, and the centroid still fails.
Slide 39 of 50: Georgia: we find regions 15× smaller. With 50 points per county the scan finds planted regions from 4.1% of the state; the centroid only succeeds at the largest size, 60.8%.
Slide 40 of 50: FlexScan and Buchin have built-in limits. FlexScan is capped at 15 regions, so it stays near 0.35. Buchin et al. needs the window size, and even given 9 sizes near the true one it is still 90× slower than ours.
Slide 41 of 50: Our windows land on the planted region: 20 trials each on Arkansas for the centroid, Buchin et al. and 50 points per county.
Slide 42 of 50: Valley Fever: within 0.036 of the best rectangle. The Point Jaccard distance to the San Joaquin Valley falls from 0.717 with the centroid to 0.448 with 50 points per county; the best rectangle reaches 0.412.
Slide 43 of 50: Conclusion: 50 points per region, not one centroid. Better than the centroid on all six maps; still fast, 0.33 s on the whole US with 50× more points; on the Valley Fever data the Point Jaccard distance falls from 0.72 to 0.45.
Slide 44 of 50: Thank you: Foad Namjoo's email, website, LinkedIn and code links, with a QR code.
Slide 45 of 50: Backup: use cases. Cancer clusters, disease outbreaks such as COVID-19, emerging public-health threats and street crime.
Slide 46 of 50: Backup: existing ways to scan regions are lossy, slow, or capped. The centroid, Buchin et al. and FlexScan compared.
Slide 47 of 50: Backup: the finest maps need the fewest points: 3 per region for the USA, 50 to 75 for Utah.
Slide 48 of 50: Backup: Theorem 3.1 bounds the points needed per region at k=O(κ / (n ε²)), with a proof sketch.
Slide 49 of 50: Backup: weighting the points by population did not help (Georgia, 50 points per county).
Slide 50 of 50: Backup: the same k in every region; the counts set the weights. DeKalb (Atlanta), 764,382 people, 15,288 per point; Taliaferro (rural), 1,559 people, 31 per point.
1 / 50 PDF

Paper

Sampling for Region-Aggregated Spatial Scan Statistics

Accepted as a full paper at ACM SIGSPATIAL 2026 — 58 of 248 submissions — and presented in Riverside, CA, on November 5, 2026. Joint work with Drew McClelland (Taptap Send), Michael Matheny (Meta), and Jeff M. Phillips.

We recommend this sampling-based conversion as the default way to apply point-based spatial scan statistics to region-aggregated data. The companion repository contains the Python experiments and figure-rendering scripts that reproduce every figure and runtime table in the paper, built on pyscan’s C++ backend.